 Parallax
An AI agent that runs written test cases on iOS and Android at the same time, a twin run, the way a tester would, judges every step honestly, and boxes the exact spot where the two apps disagree.
Work in progress. This page follows what is built so far.
Parallax is named after the optical effect it works by: one thing seen from two positions, where the shift between them is the finding. Here the one thing is a test case, the two positions are iOS and Android, and running them side by side is a twin run.
The problem
Most mobile QA teams keep their regression suites as written steps with expected results (“open the cart, remove the item, the total goes to zero”) and run them by hand, once per platform. That costs three things:
- Manual regression is slow, so it is the first thing cut when a release is late.
- Scripted automation is brittle. XCUITest, Espresso and Appium scripts hard-code selectors and timing, so automating the cases means maintaining selectors for two apps that change every sprint.
- Nobody compares the platforms. iOS and Android are usually tested separately, by different people on different days, so the step that works on iOS and quietly does something else on Android ships.
The tools that run plain-language cases with AI mostly test one platform at a time, so they miss exactly that last kind of bug.
What it does
- Reads the test cases as written, from Markdown, YAML or a mind map, into one platform-neutral plan.
- Runs each case on iOS and Android at once, in step: a twin run. Neither platform starts step N+1 until both have finished step N, so the two runs can be compared step by step. A platform that gets stuck times out and stops; the other carries on.
- Works like a tester. For each step it looks at the screen, decides what to do, does it through Appium, looks again, and checks the result against the step’s expected outcome.
- Says honestly what happened. Every step ends as pass, fail (a real issue), or blocked with a typed reason: an ambiguous step, an element it couldn’t find, an unexpected screen, a precondition that wasn’t met, or something that needs a person. A blocked step is never counted as a pass.
- Boxes the evidence. A failure or a divergence is drawn on the screenshot around the element that proves it, and repeats of one problem are grouped into a single finding.
- Reports as a self-contained HTML page (the distinct findings first, then every step side by side with its screenshots), a
junit.xmlfor CI and a JSONL event log, with the token use and cost of the run. It exits non-zero when anything failed, blocked or diverged.
What it found
The reference app is Sauce Labs’ public My Demo App, which ships as two separate native codebases (Swift and Kotlin, v2.3.0). Five test cases, written once and run on both platforms, surfaced four real differences. None of them is described in the knowledge the agent was given, and each was confirmed by hand.
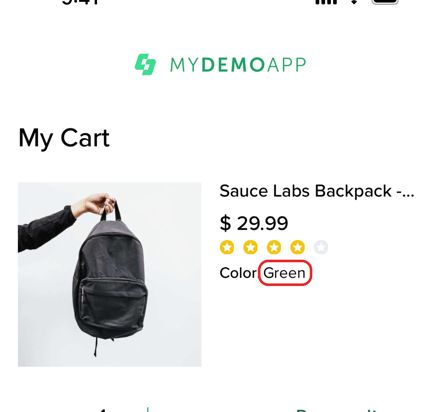
The cart says "Color: Green" under a black backpack.
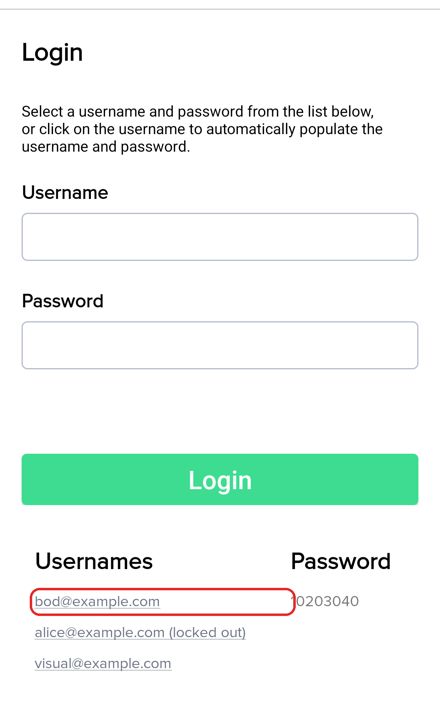
The demo login lists "bod@example.com", not bob@.
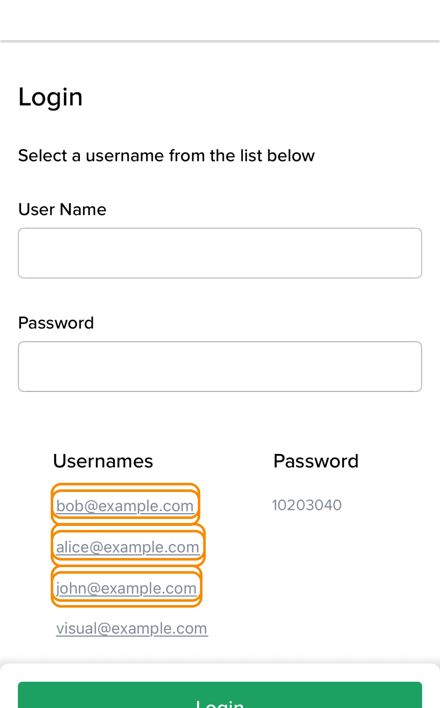
bob, alice and john@ on iOS…
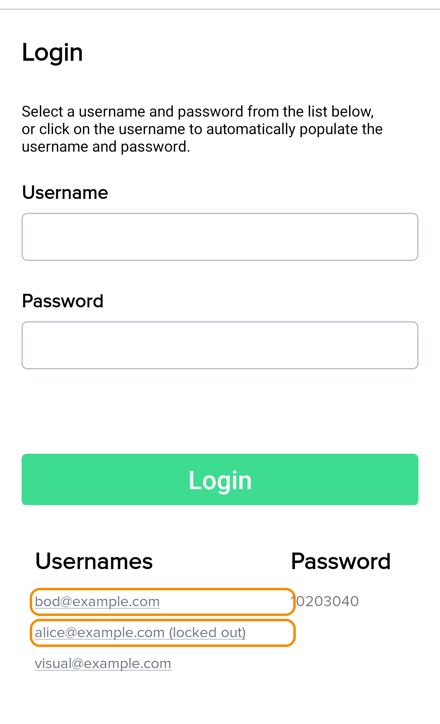
…bod, and alice "locked out", on Android.
The other two came from the comparator alone: iOS pre-selects the green swatch on the black backpack while Android pre-selects black, and the builds name products differently, so one sweater is “T-Shirt - Red” on iOS and “T-Shirt (pink)” on Android and sorting Z to A gives a different order.
How it fits together
Claude plays three roles, each with one job and a JSON answer. An answer that isn’t valid JSON gets one corrective retry before it counts as an error.
| Role | Sees | Returns | If it can’t answer |
|---|---|---|---|
| Reasoner | the screen with numbered tap targets, the element list, the step, app knowledge, what earlier turns did | actions for this screen, and whether the step is done | blocked, with a typed reason |
| Verifier | the screens before and after the step, the elements, the expected result | pass or fail, what it saw, its confidence, and the element that proves it | fail, confidence 0 |
| Comparator | both platforms’ screens and elements, both verdicts, the expected differences | each difference, suspicious or expected, with evidence on each side | “review manually”, never dropped |
How it reads a screen
Every observation combines the accessibility tree, which says what each element is and exactly where it sits, with the screenshot, which carries colours, images and layout. These are real output from one observation of the iOS catalog:
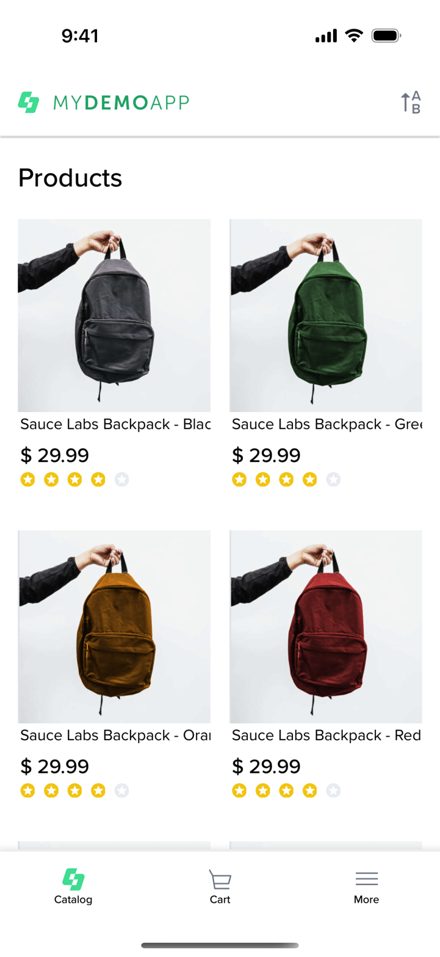
Wait until the screen stops changing, then capture.
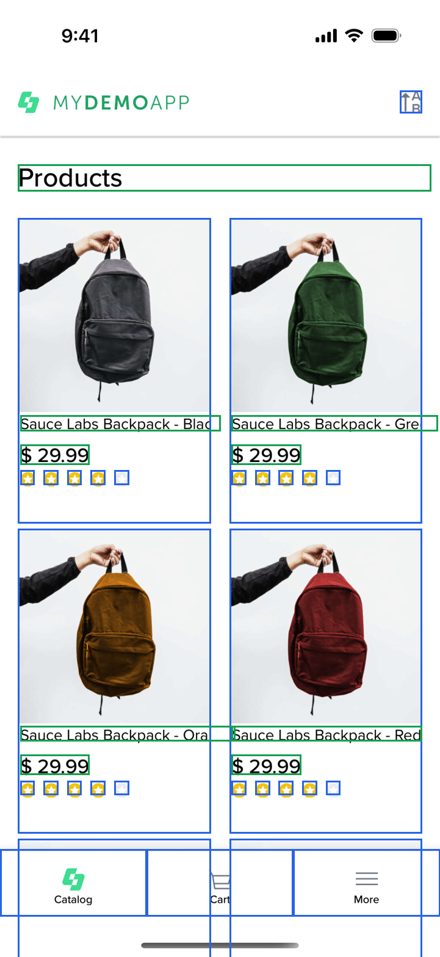
One page-source read (0.4 s): 30 tap targets, 9 texts.
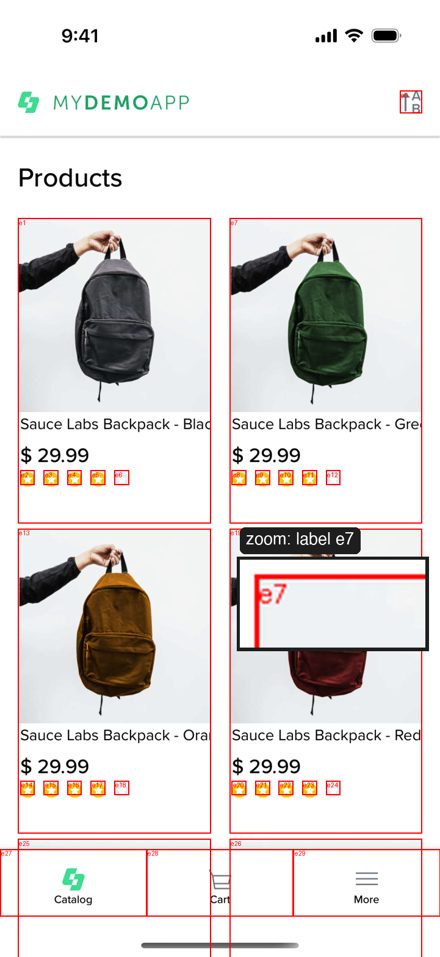
Numbered boxes: exactly what the reasoner sees.
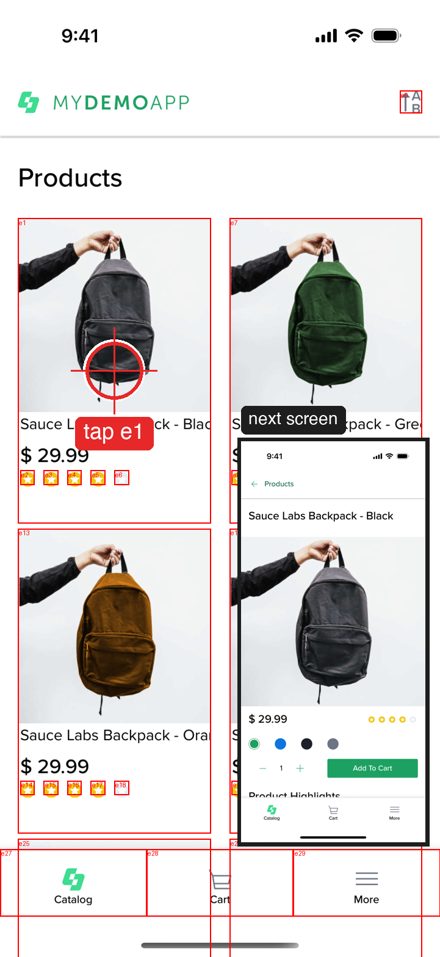
It answers "tap e1"; the tree gives the position.
The model never supplies coordinates: it names an element, and the tree supplies the position. With the elements removed, the verifier still judged the cart correctly from pixels alone, but its estimated evidence box missed the “Color: Green” label by a wide margin, which is why taps and boxes are anchored to the tree whenever it exists.
Games, canvas and custom-drawn screens have no tree, and at first every tap on them ended blocked. Now such a screen reaches the reasoner as a numbered 6 × 12 grid. On the Android catalog with its elements removed, for “Open the cart”:
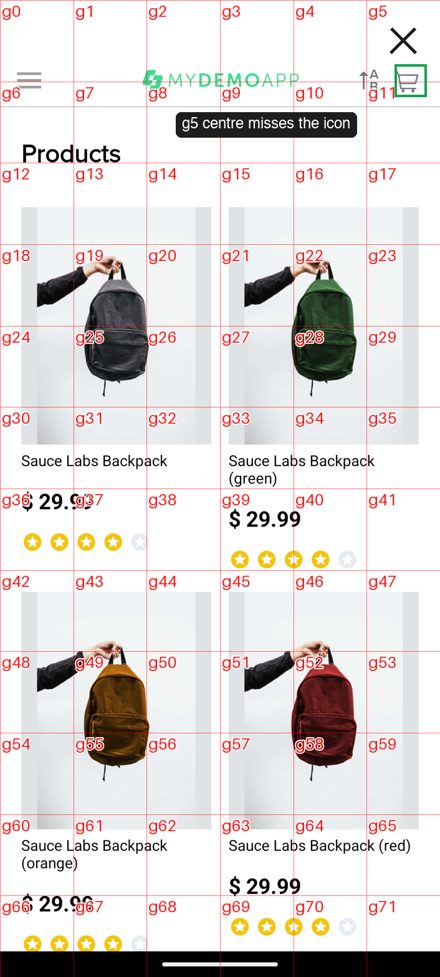
The icon straddles two rows, so the centre of g5 misses it.
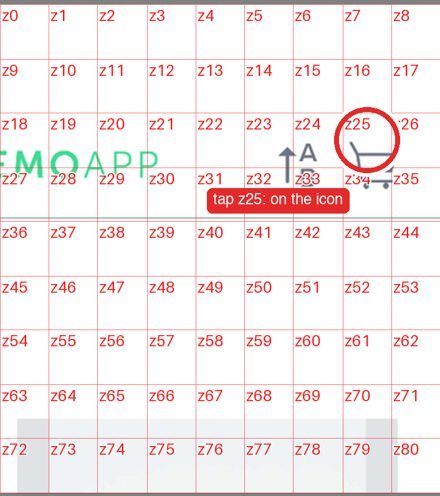
A close-up split 9 × 9: z25 is on the icon.
The first version tapped cell centres and passed this case 1 time in 3. One extra model call on the close-up now puts the tap within about a third of a cell. Typing still needs a real field, so it stays blocked.
How a step runs
A step runs as a closed loop: look at the screen, act on what is actually there, look again. “Tap the first product, then tap Add To Cart” spans two screens, so it takes two turns; before the loop existed, steps like that failed on both platforms. When the step is done, a separate verifier compares the screens from before and after with the expected result.
Comparing the platforms
Once both platforms finish a step, the two results are compared. Anything code can decide is decided in code; only the fuzzy part goes to a model.
The comparator is scoped to the step, so an unrelated difference elsewhere on the screen isn’t that step’s divergence, and the pack’s rules mark the differences that are known and expected.
Measured, not assumed
Every prompt or model change goes through an eval suite of 27 labelled cases built from real recorded screens, with no device needed. Checks are properties, never exact strings: the verdict matches the label, the right difference is flagged and names the key facts, the right element is targeted or cited, and nothing that matches the expectation is cited as evidence. Each case runs three times, because model output varies.
The verifier has passed every run of every version with zero false passes; the comparator is where the work was:
| Version | What changed | Comparator |
|---|---|---|
| v1 | first suite | 15/18 |
| v3 | must cite the right element as evidence | 14/18: the gate caught 2 regressions |
| v4 | element list shows text and id (a selected swatch read as just “1”) | 18/18 |
| v6 | trial of a newer model: 2–3× faster, 82% higher cost | 17/18, rejected |
| v8 | the reasoner types secret placeholders literally | 21/21 |
| v10 | two comparator prompt rules tried and reverted | 18/18, plus 1 known failure |
That known failure is the Red/Pink sort: the comparator flags it with the right evidence but explains it as a product missing on Android. A prompt rule asking it to check for renamed items didn’t change that (0 of 3), so the rule was reverted and the case is tracked as a known failure. It runs every time and is reported apart, but doesn’t gate other changes.
Live runs, before and after
| First live run | Now | |
|---|---|---|
| Cross-platform check | exact text of two descriptions | the comparator, scoped to the step |
| Divergences flagged | 8, of which 7 false | all real, repeats grouped |
| Step spanning two screens | failed on both platforms | works; iOS then fails on the real colour defect |
| Wrong verdicts | — | 0 in the last 46 step runs |
| One case, both platforms | — | about 75 s |
| Full five-case suite | $0.71 | about $1.00 and 7–9 minutes |
Some fixes only a real device revealed:
- UiAutomator2 reports an element’s label where its type should be.
- Reading a screen took about 160 WebDriver calls; one page-source read is about 12× faster.
- On a slow emulator the pixels lag the accessibility tree, and right after a tap the old screen can look settled, so a frame is taken only once the screen has changed and stopped changing.
- The Android automation server dropped about once per run. The driver now reconnects once, without restarting the app, and retries; tested by killing the server mid-case.
- My own MCP servers loaded their tool definitions (about 33k tokens) into the agent’s model calls about a third of the time, doubling the cost of a run. Isolating them halved it.
Decisions worth explaining
Domain knowledge lives in packs, not in the agent
Every app has its own navigation, jargon and quirks. A knowledge pack is a folder per app: how to get around, a glossary, known quirks, reusable flows such as logging in, stable selectors, test accounts, and the platform differences that are expected (“the cart is a bottom tab on iOS and a header icon on Android”). Expected differences are suppressed; everything else stays suspicious. The agent picks the pack by the app’s bundle id, so onboarding a new app means writing a pack, not changing the agent. The demo app’s pack describes how to use it and says nothing about its defects.
Passwords never reach the model
Test-account passwords are kept out of every prompt and log. The model only ever sees a placeholder in a flow step, like {password} or a one-time code’s {otp}, and types the placeholder itself; the real value is swapped in by the driver at the moment of typing and redacted from the step’s record afterwards. Secret values are also redacted from element text the model sees, and of the test accounts only usernames and emails reach the model at all. The accepted risk is the screenshot itself, which can show a typed value.
Blocked is not the same as failed
An agent that can’t find a button and an app that is broken look the same if every problem is a failure. Separating “the app is wrong” from “I couldn’t do this step, and here’s why” is what makes the results worth trusting, and it tells you whether to fix the app or the test case. A pass the verifier gives with low confidence is flagged for a person to look at.
Differences are judged, not diffed
Comparing the text each platform showed word for word flagged every harmless difference: two model descriptions of two screens never match exactly, so 7 of the first 8 divergences were false. A model now compares the two outcomes, looking at both screens, and says whether they mean the same thing; a difference in status (one passed, one failed) is still decided in code, with no model call.
Evidence anchored to the tree
The model cites an element; the box is drawn from that element’s real bounds. Only when there is no tree is a box an estimate, and then it is drawn dashed. One problem seen on several steps is grouped into one finding by the on-screen text its evidence cites, so the count reflects problems, not steps.
Measured on recorded screens
The three model roles are scored offline on real recorded screens, with no device needed, so a prompt change can be checked before a live run. Every behaviour that went wrong in a live run is added to that suite before it is fixed, and a measured weakness the suite can’t yet pass stays visible as a known failure instead of being quietly dropped.
Where it is
Running end to end on both platforms against the demo app: 316 unit tests that need no device or API key and run on every pull request (the workflow is annotated on How I work), 27 eval cases, and about a dollar per full run on a Claude subscription. It sets itself up too: qa-agent doctor diagnoses the environment and prints the fix for anything missing, and qa-agent demo installs the demo app and writes the config.
Known limits: the grid fallback has only been tested on recorded screens, not on a live app without a tree, and the reference cases were written after exploring the app, so cases written blind would be a stronger test. Next: the cloud device farm the device layer was designed for.